
TL:DR
- Falling AI model prices are driving higher enterprise costs as token consumption grows, with orchestration, retrieval & system overhead far outweighing model invoice expenses.
- Intelligent routing optimizes AI costs by directing each workload to the best-fit model based on economics, performance & trust, reducing unnecessary model calls & data movement.
- A vendor-neutral digital infrastructure foundation preserves model choice & workload flexibility, enabling enterprises to adapt as models, prices & demand evolve.
The cost of enterprise-class AI models is falling rapidly. But describing tokens themselves as a commodity is only half right. A token is a billing meter, not a standardized unit of intelligence. One million tokens from one model may not deliver the same business result as one million from another, from a capability, reliability or latency perspective. What’s becoming commodity-like is the metered intelligence that enterprises can increasingly source across model providers.
DeepSeek’s V4 pricing illustrates this shift. V4 Flash mode offers discounts of up to 99% off frontier model pricing for comparable coding work, alongside peak and off-peak pricing.[1] This is the early formation of a dynamic market that prices intelligence by capability, demand and availability.
For enterprises, however, more choice does not automatically translate into lower costs or greater control. To understand why, they must look beyond the price of the model.
What’s really driving higher AI costs?
AI economics is driven by both unit cost and consumption. The supply of affordable models is increasing, but demand is increasing even faster. AI is entering its own version of the Jevons paradox: As the unit cost of intelligence falls, organizations discover more uses for it, such as larger contexts, more users, more workflows and increasingly autonomous agents. Token prices can therefore fall while the total AI bill continues to rise.
According to one estimate from NavyaAI Research, the model invoice only accounts for 28% of total production AI costs. The remaining 72% comes from things like orchestration, retrieval, retries and observability.[2] A model that’s inexpensive in terms of cost per million tokens may still be the more expensive choice if it delivers lower-quality answers, requires repeated calls, creates the need for additional human review, or forces data to move inefficiently between environments.
The equation is straightforward: Total cost is driven by unit cost, consumption volume and AI system overhead. Organizations that manage only the first variable will overlook the other two and capture only part of the available cost optimization.
From token budgets to outcome economics
Token budgeting is an investment allocation problem, not merely a procurement exercise. Every token should be evaluated according to the business outcomes it helps produce.
Think of AI consumption as choosing transportation for each trip. The task is the destination, models are different vehicles, and tokens are the fuel or fare. You wouldn’t hire a limo to travel two blocks, just like you wouldn’t use a bicycle to move a family across the country. The right decision depends on the journey, not just on which vehicle has the lowest cost per mile.
Similarly, routine classification, summarization and retrieval tasks may be handled by smaller, less expensive models. Complex reasoning, regulated decisions or high-value customer interactions may justify a premium model. There must be a router to act as the dispatcher, continuously matching each journey to the appropriate vehicle, route and service level.
Enterprises can neither predict nor control the changes in the AI model marketplace. But what they can control is the architecture through which they access that market. Infrastructure designed for neutrality, flexibility and model choice creates bargaining power, resilience, and the freedom to place every workload where economics, performance and trust are best aligned.
Future-readiness comes from preserving the freedom to adapt as models, prices and demand evolve. Yet most enterprise architectures are built in ways that restrict this agility. There are three warning signs that indicate your stack may be falling behind:
- Slow adoption of better models: You see superior alternatives on the market, but swapping out your existing model requires a major engineering overhaul.
- Deep vendor lock-in: Data pipelines, orchestration and guardrails are tightly coupled to one provider’s ecosystem, creating prohibitive switching costs.
- Demand controls are weak: Multi-step agents can multiply model calls, tool invocations, retries and validation cycles. Without effective caching, context management, retry limits and loop controls, consumption can quickly exceed forecasts.
To overcome these challenges, enterprises must build an infrastructure environment that treats every model as architecturally replaceable. When a better or more economical model emerges, they need flexibility to redirect appropriate workloads without rebuilding the surrounding architecture.
This concept of dynamic workload routing for AI is quickly emerging as an architectural discipline. But to truly move the needle on AI costs, enterprises need intelligent routing, and a vendor-neutral infrastructure foundation that can execute those routing decisions across clouds, models, infrastructure and sovereign environments.
What is intelligent routing? How can it support lower AI costs?
Intelligent routing means sending each workload to the model that’s the best fit to support it.
“Best fit” should be determined across enterprise priorities. For example:
- Economics: Token price, infrastructure utilization, data-movement costs, and the probability of retries
- Performance: Answer quality, latency, throughput, availability, and proximity to users and enterprise data
- Trust: Security, privacy, sovereignty, explainability, and policy compliance
A routing solution is “intelligent” when it can keep track of changing real-time conditions and update its decisions accordingly. This means sending workloads to the right model for right now, not the one you picked months ago.
In turn, architecting for flexibility and model choice will grow even more important, because enterprises will need digital infrastructure that helps them make the most of their routers. They’ll need a neutral infrastructure foundation, on-demand connectivity solutions, and access to a dense ecosystem of AI partners. The most important strategic decision is therefore not predicting which model will win; it’s building the platform that benefits from competition among all of them.
To control AI costs, start by controlling workload placement
Intelligent routing can help enterprises optimize cost-efficiency through three levers:
- Model selection: Broaden access to approved models and providers, then direct each task to the lowest-total-cost model that meets its capability, quality, latency and trust requirements.
- Workload placement: Run inference in the environment that best balances compute costs, data locality, performance and sovereignty. This reduces avoidable data movement and egress fees.
- Demand reduction: Avoid unnecessary model calls through semantic caching, efficient context management, stronger retrieval, and controls on retries and agent loops.
These levers depend on both software orchestration and infrastructure. The router identifies the preferred destination; a neutral, connected infrastructure foundation makes that destination reachable and preserves the enterprise’s ability to change course as models and economics evolve.
Semantic caching is particularly effective for high-volume, repetitive requests whose answers remain stable. For example, an IT chatbot that frequently helps users with simple tasks like resetting passwords or installing VPNs could pull from a cached set of instructions instead of calling an LLM. This directly leads to significantly lower token consumption, since the simplest prompts tend to be the most commonly used. According to AWS benchmarks, semantic caching reduces LLM inference costs by up to 86%.[3]
Enterprises also control where the cache is hosted, which means they can position it in proximity to the application. This allows them to return responses with much lower latency compared to calling an LLM.
Who controls the routing criteria matters
Provider-native routers can be highly effective within their own ecosystems. The strategic question is whether their “best fit” matches the enterprise’s “best fit.” What’s most important is not who owns the model, but who controls the routing criteria.
A single-provider architecture may simplify operations and could be appropriate for some workloads. The tradeoff is greater concentration risk, narrower model choice, and less freedom to respond when prices, capacity, performance or policies change. Spending can still be governed, but the enterprise has fewer alternatives when its original assumptions no longer hold.
The internet offers a useful historical precedent. It scaled because independently operated networks could interconnect at neutral exchange points while retaining their own commercial interests and routing policies. This is exactly what Equinix was founded to provide. Our colocation data centers became vendor-neutral internet exchange points that helped make the modern internet possible.
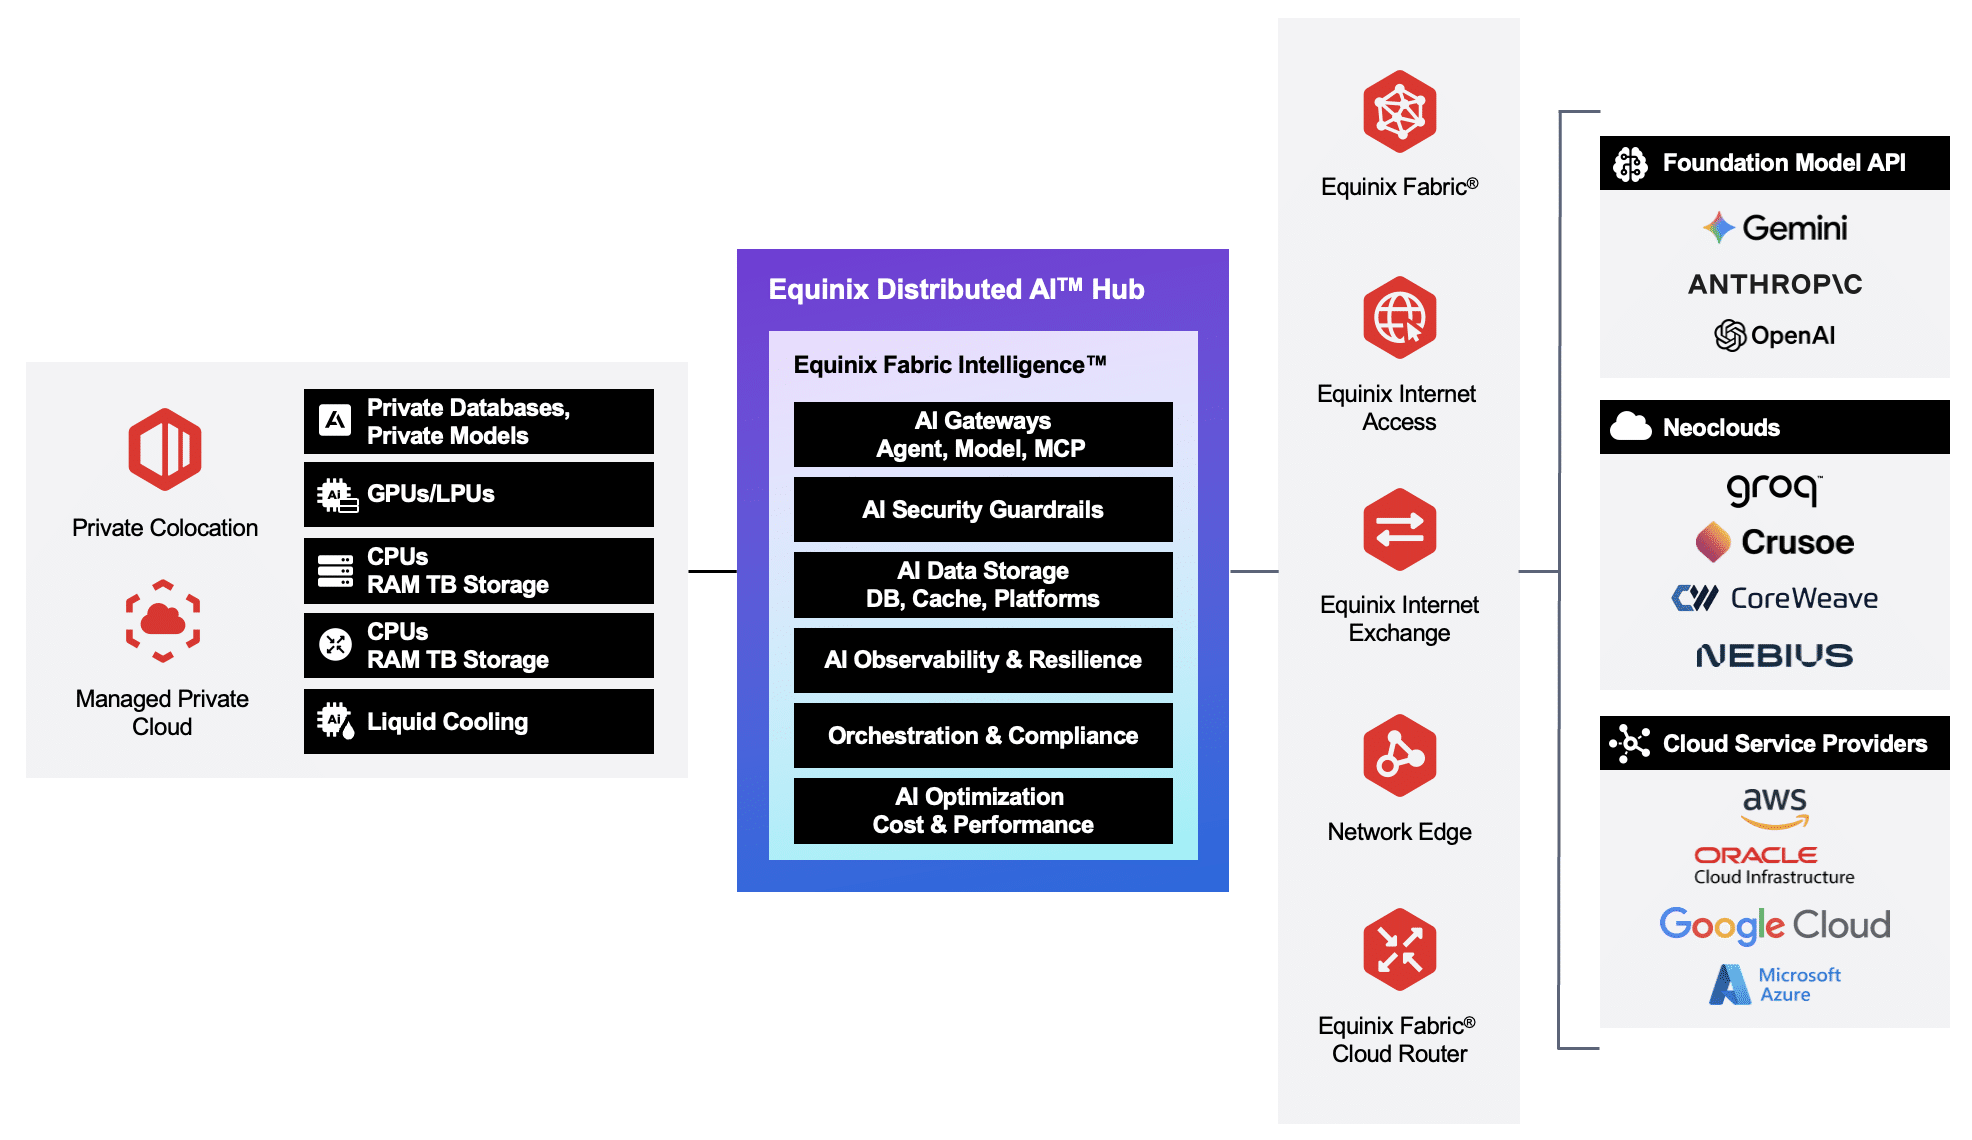
AI is approaching a similar inflection point. Models, clouds, neoclouds, private infrastructure, networks and enterprise data must interconnect without forcing the enterprise into a single technology stack. This vendor-neutral AI ecosystem is already forming at Equinix: As of 2026, 8 out of the top 10 AI model providers and 4 out of the top 5 neoclouds are deployed inside Equinix data centers. Equinix’s role is not to choose a model on the customer’s behalf. It is to provide the neutral interconnection and workload-placement foundation that makes customer choice actionable.
Equinix is also home to network service providers that enable the global high-bandwidth connectivity that AI demands. For instance, Zayo brought their 400G-enabled network backbone to Equinix’s global data center footprint. Together, we enable speed, scale and reliability for AI workloads.
This partnership ensures our shared customers have immediate, seamless access to the high-performance communications infrastructure that is absolutely essential for rapidly deploying, managing and scaling their critical AI initiatives effectively.”Aaron Werley, Senior Vice President, Zayo
How Equinix can help
Equinix provides the neutral, distributed infrastructure foundation that enables enterprises to implement intelligent routing across clouds, model providers, private infrastructure and sovereign environments:
- Our colocation data centers provide a global, vendor-neutral foundation on which to deploy the router.
- Our interconnection solutions enable flexible, scalable connectivity to support distributed AI workloads. For instance, Equinix Fabric Intelligence™ provides real-time visibility into changing conditions and enables the network to adapt itself accordingly.
- The Equinix Distributed AI™ Hub is a single unified framework that connects distributed data sources with AI ecosystem partners, including major model providers.
 Learn more about how AI-native networking enables the flexibility enterprises need to control and optimize their AI workloads: Read the white paper “Why intelligent networks are essential in the AI era.”
[1] Zachary Basu and Madison Mills, DeepSeek’s new bargain model accelerates AI’s race to zero, Axios, August 1, 2026.
[2] AI Cost Report 2026: Token Prices & Rising AI Bills, NavyaAI Research, February 2026.
[3] Overview of semantic caching, Amazon ElastiCache.

 Subscribe to the Equinix Blog